Comprehension
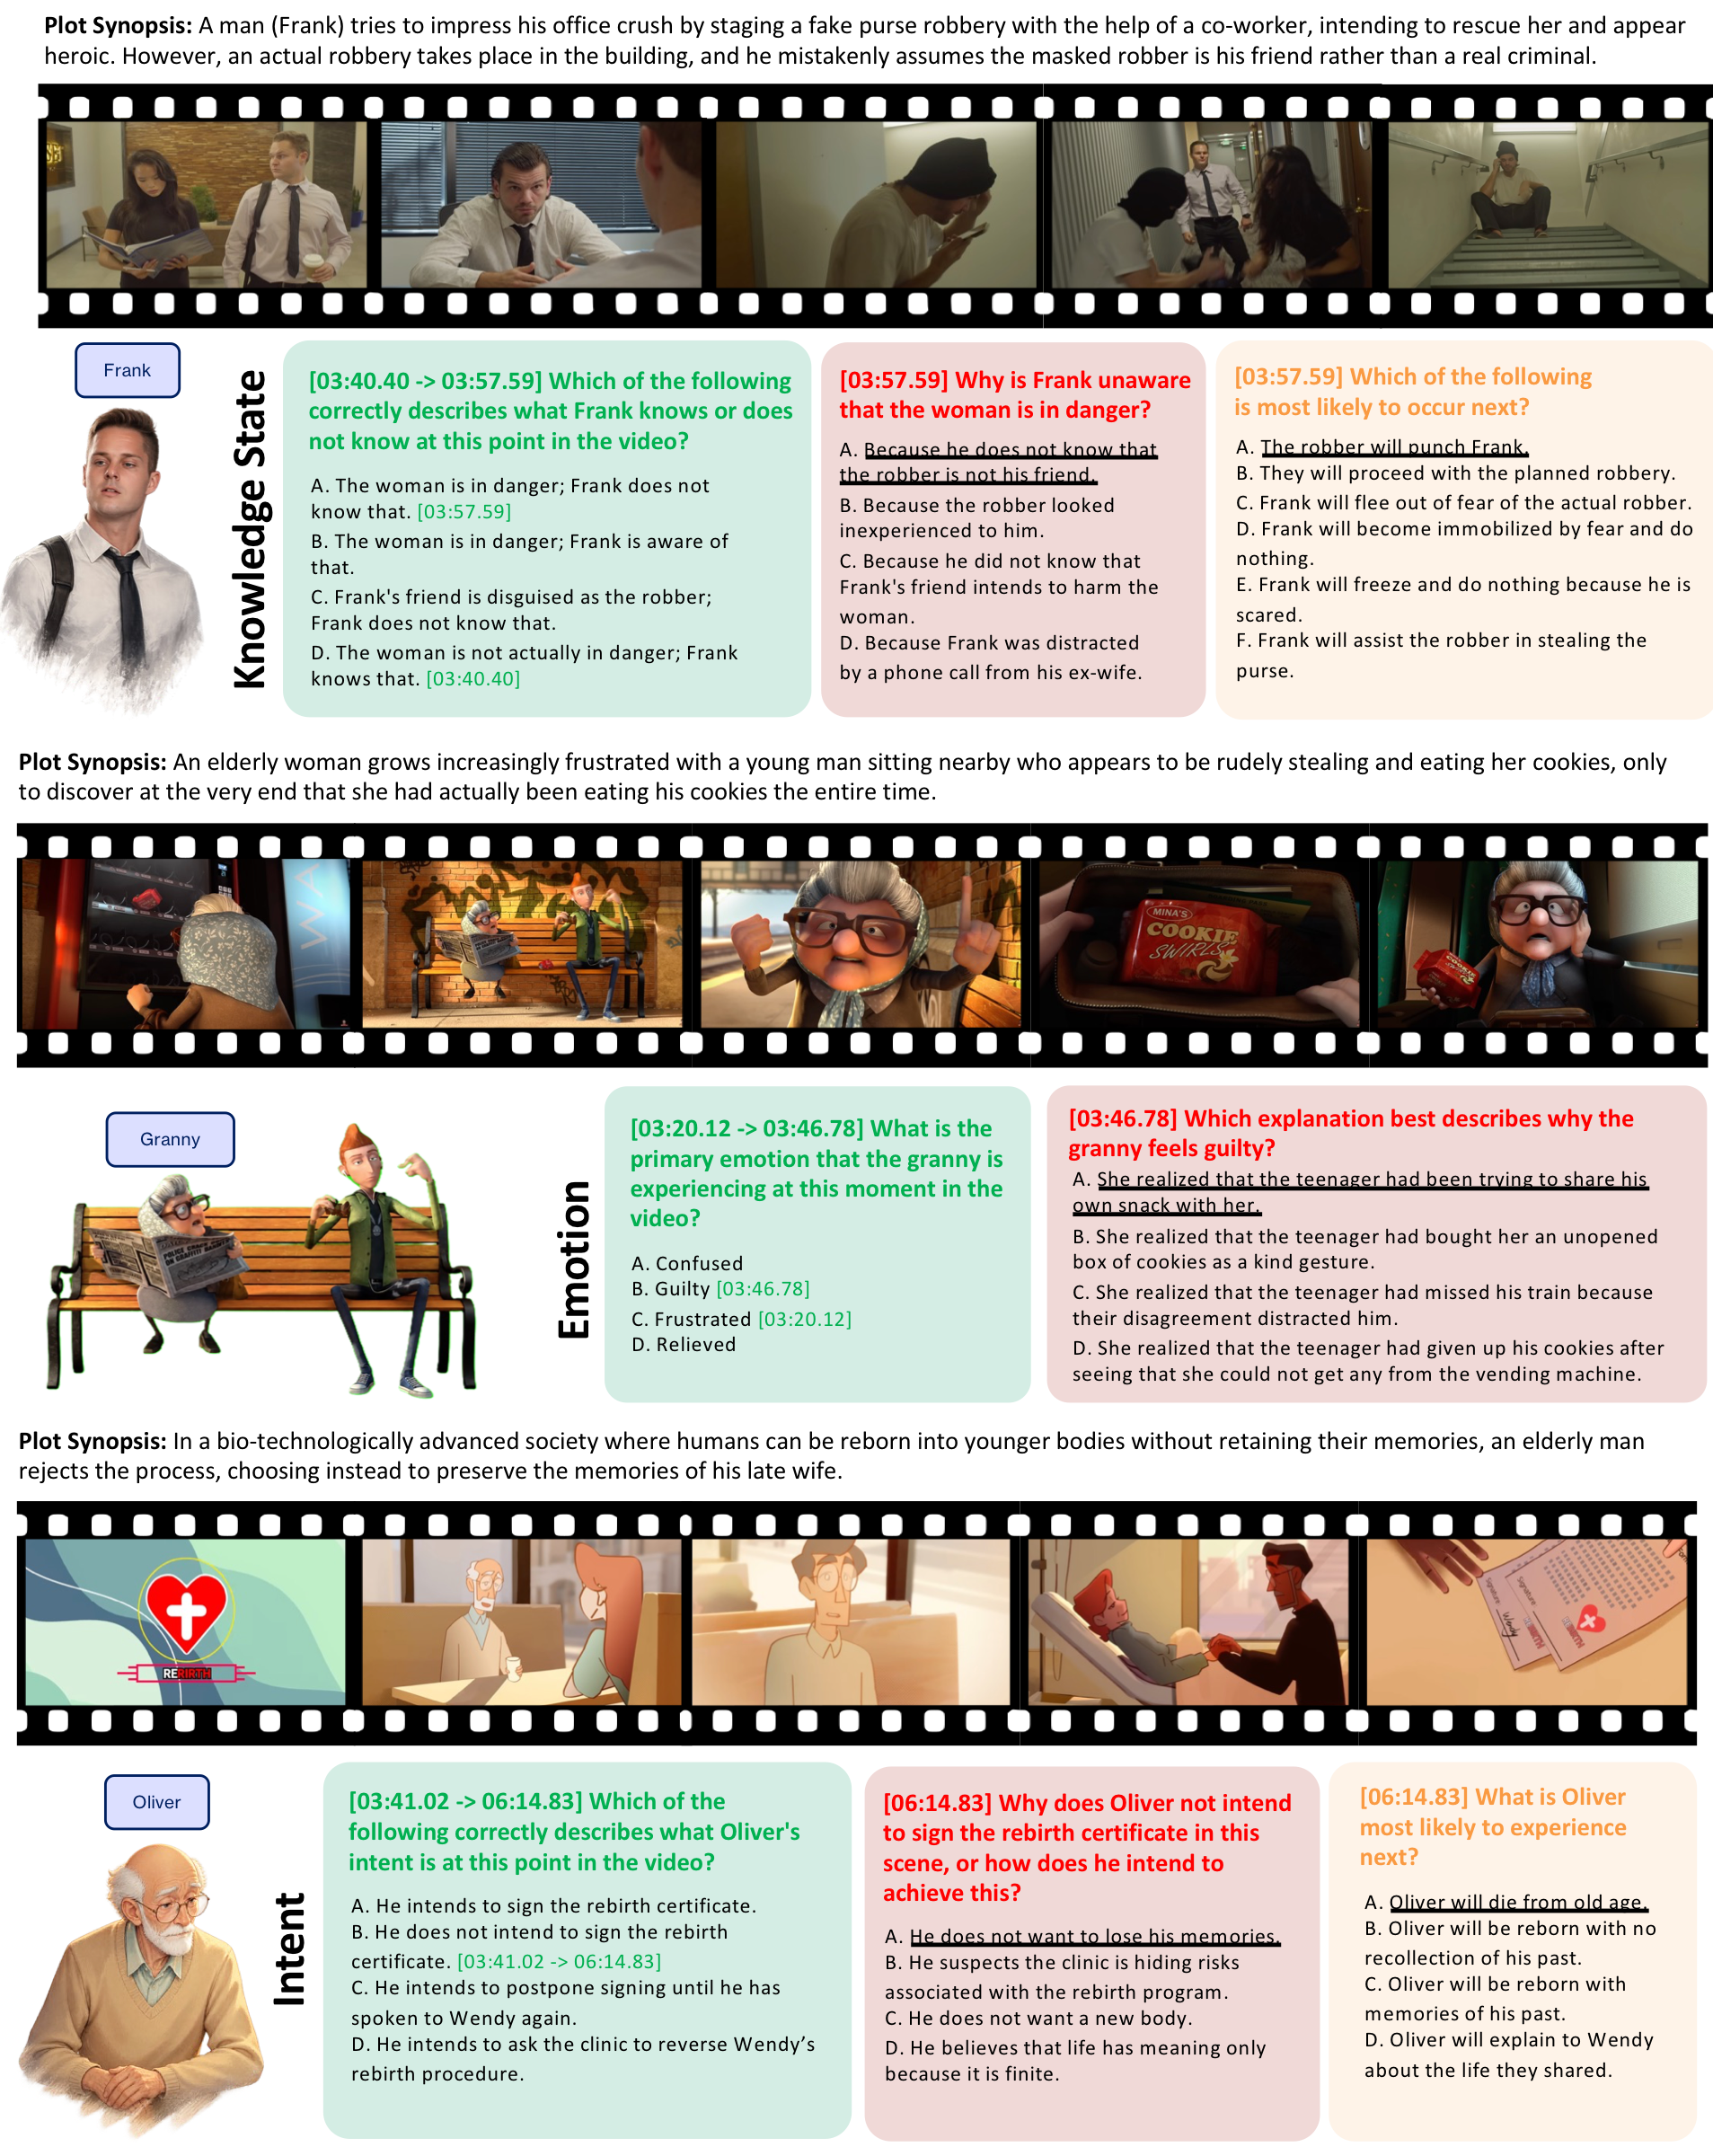
Recognize what is happening at a specific social moment.
TL;DR
Does your model understand complex social interactions over long horizons as the video unfolds?
Can your model reason correctly about visual clues in long-horizon videos?
Can your model behave appropriately in various social contexts?
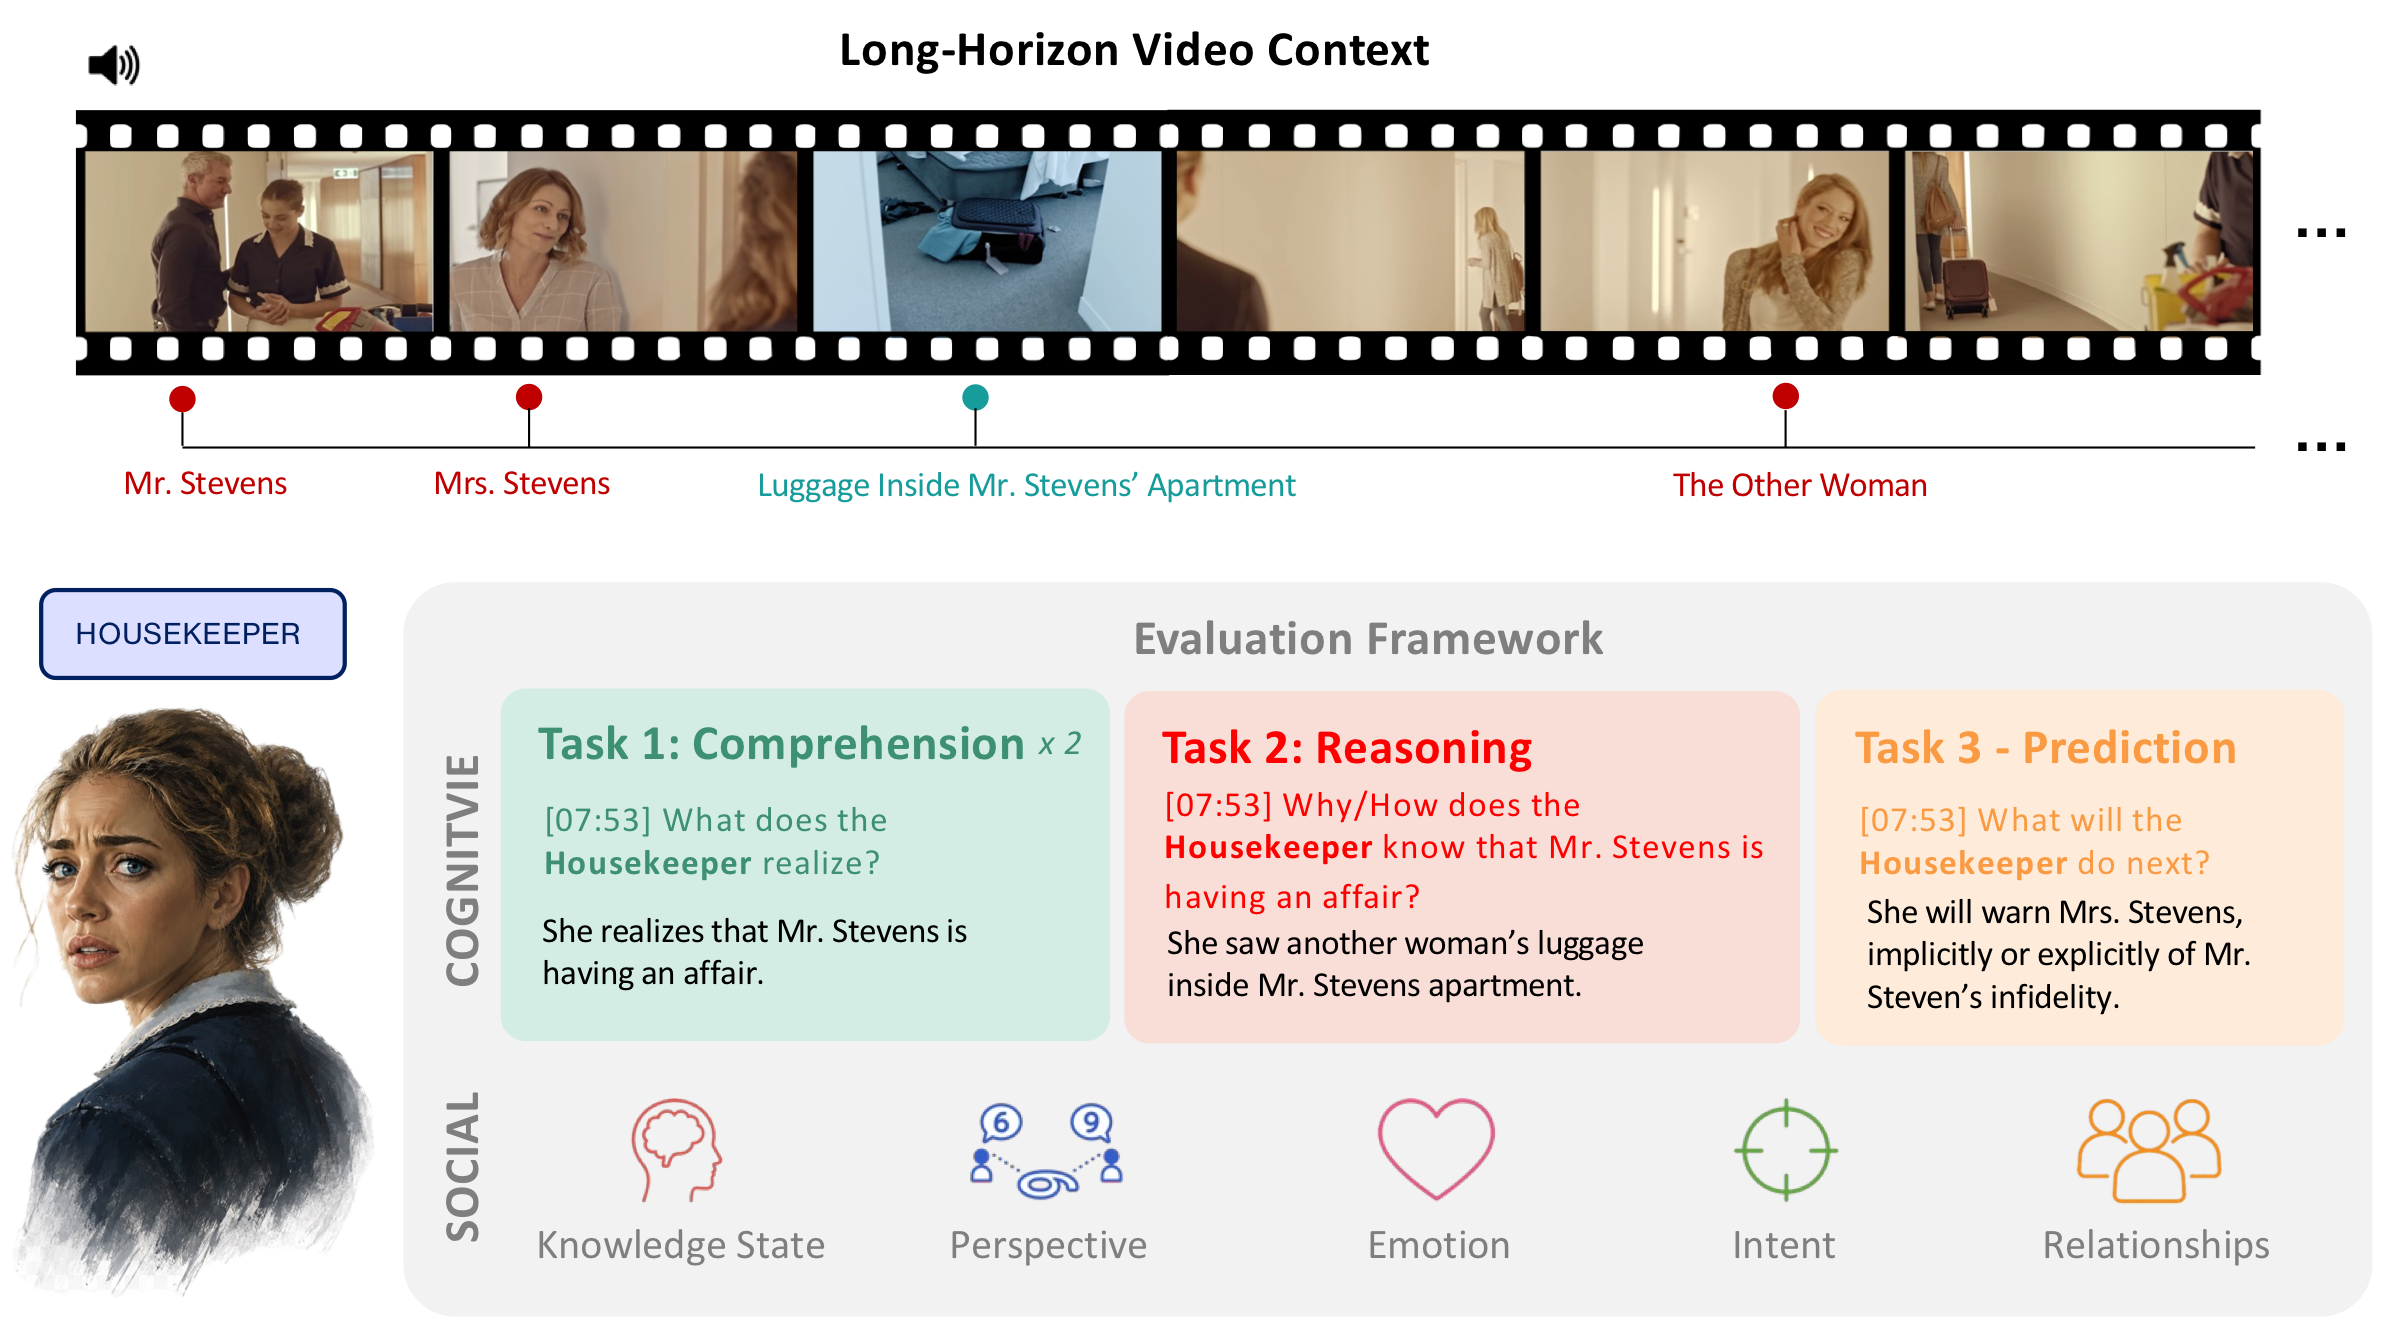
Recognize what is happening at a specific social moment.
Explain the social evidence behind an interpretation.
Anticipate what is most likely to happen next.
Human understanding of character emotions, intent, perspectives, knowledge states, and relationships evolves as video context unfolds. However existing papers only ask independent MCQs.
Comprehend the situation before the pivotal event.
Reason about the visual evidence that changes the interaction.
Comprehend the situation after the event and update the representation.
Predict the appropriate next behavior from the updated state.
Both comprehension checkpoints and reasoning must be correct.
C0 ∧ C1 ∧ R
A correct prediction must also show the model can act on its updated social representation. (e.g. Correct Comprehension, Wrong Reasoning)
SUS ∧ P
No partial score is awarded for partial understanding.
Even the strongest multimodal model trails the human baseline on joint social understanding and agency. Explore performance across every cognitive task and social dimension.
Scroll horizontally to inspect every metric. Values are proportions; higher is better.
Test your Social Intelligence? Click on any video. The video will pause automatically to ask you questions at particular moments. Answer the questions to continue with the rest of the video.
If SMMU supports your research, please cite the project. Final publication details will replace this placeholder.
@misc{smmu2026,
  title  = {SMMU: Benchmarking Social Intelligence of Multimodal Large Language Models},
  author = {SMMU Authors},
  year   = {2026},
  note   = {Placeholder citation - final bibliographic details forthcoming}
}